Categories &
Functions List
- adtest
- anova
- anova1
- anova2
- anovan
- ansaribradley
- barttest
- binotest
- chi2gof
- chi2test
- correlation_test
- detectdrift
- dwtest
- fishertest
- friedman
- hotelling_t2test
- hotelling_t2test2
- jbtest
- knntest
- kruskalwallis
- kstest
- kstest2
- lillietest
- manova1
- mcnemar_test
- meanEffectSize
- mmdtest
- multcompare
- ranksum
- regression_ftest
- regression_ttest
- runstest
- signrank
- signtest
- stats.drift.DriftDiagnostics
- swtest
- ttest
- ttest2
- vartest
- vartest2
- vartestn
- ztest
- ztest2
- CompactLinearModel
- CoxModel
- coxphfit
- fitcox
- fitglm
- fitglme
- fitlm
- fitlme
- fitlmematrix
- fitnlm
- fitrm
- GeneralizedLinearMixedModel
- GeneralizedLinearModel
- glmfit
- glmval
- invpred
- lasso
- lassoglm
- LinearFormula
- LinearMixedModel
- LinearModel
- logistic_regression
- mnrfit
- mnrval
- monotone_smooth
- mvregress
- mvregresslike
- nlinfit
- nlparci
- nlpredci
- NonLinearModel
- plsregress
- regress
- regress_gp
- RepeatedMeasuresModel
- ridge
- robustfit
- stepwisefit
- stepwiseglm
- stepwiselm
- ClassificationBaggedEnsemble
- ClassificationDiscriminant
- ClassificationECOC
- ClassificationEnsemble
- ClassificationGAM
- ClassificationKernel
- ClassificationKNN
- ClassificationLinear
- ClassificationNaiveBayes
- ClassificationNeuralNetwork
- ClassificationPartitionedECOC
- ClassificationPartitionedEnsemble
- ClassificationPartitionedKernel
- ClassificationPartitionedLinear
- ClassificationPartitionedModel
- ClassificationSVM
- ClassificationTree
- CompactClassificationDiscriminant
- CompactClassificationECOC
- CompactClassificationEnsemble
- CompactClassificationGAM
- CompactClassificationNaiveBayes
- CompactClassificationNeuralNetwork
- CompactClassificationSVM
- CompactClassificationTree
- CompactRegressionGAM
- CompactRegressionEnsemble
- CompactRegressionGP
- CompactRegressionNeuralNetwork
- CompactRegressionSVM
- CompactRegressionTree
- CompactTreeBagger
- designecoc
- fcnnpredict
- fcnntrain
- fitcdiscr
- fitcecoc
- fitcensemble
- fitcgam
- fitckernel
- fitcknn
- fitclinear
- fitcnb
- fitcnet
- fitcsvm
- fitctree
- fitrensemble
- fitrgam
- fitrgp
- fitrkernel
- fitrlinear
- fitrnet
- fitrsvm
- fitrtree
- gamboostinter
- gamboostpairs
- gamboostpredict
- gamboosttrain
- gampredict
- gamtrain
- partialDependence
- plotPartialDependence
- PredictiveModel
- RegressionBaggedEnsemble
- RegressionEnsemble
- RegressionGAM
- RegressionGP
- RegressionKernel
- RegressionLinear
- RegressionNeuralNetwork
- RegressionPartitionedEnsemble
- RegressionPartitionedKernel
- RegressionPartitionedLinear
- RegressionPartitionedModel
- RegressionSVM
- RegressionTree
- lime
- shapley
- svmpredict
- svmtrain
- templateDiscriminant
- templateEnsemble
- templateKernel
- templateKNN
- templateLinear
- templateNaiveBayes
- templateSVM
- templateTree
- TreeBagger
- treepredict
- treetrain
- paretotails
- prob.ProbabilityDistribution
- prob.BetaDistribution
- prob.BinomialDistribution
- prob.BirnbaumSaundersDistribution
- prob.BurrDistribution
- prob.ExponentialDistribution
- prob.ExtremeValueDistribution
- prob.GammaDistribution
- prob.GeneralizedExtremeValueDistribution
- prob.GeneralizedParetoDistribution
- prob.HalfNormalDistribution
- prob.InverseGaussianDistribution
- prob.KernelDistribution
- prob.LogisticDistribution
- prob.LoglogisticDistribution
- prob.LognormalDistribution
- prob.LoguniformDistribution
- prob.MultinomialDistribution
- prob.NakagamiDistribution
- prob.NegativeBinomialDistribution
- prob.NormalDistribution
- prob.PiecewiseLinearDistribution
- prob.PoissonDistribution
- prob.RayleighDistribution
- prob.RicianDistribution
- prob.StableDistribution
- prob.tLocationScaleDistribution
- prob.TriangularDistribution
- prob.UniformDistribution
- prob.WeibullDistribution
- betafit
- betalike
- binofit
- binolike
- bisafit
- bisalike
- burrfit
- burrlike
- copulafit
- evfit
- evlike
- expfit
- explike
- gamfit
- gamlike
- geofit
- gevfit
- gevlike
- gevfit_lmom
- gpfit
- gplike
- gumbelfit
- gumbellike
- hnfit
- hnlike
- invgfit
- invglike
- logifit
- logilike
- loglfit
- logllike
- lognfit
- lognlike
- nakafit
- nakalike
- nbinfit
- nbinlike
- normfit
- normlike
- poissfit
- poisslike
- raylfit
- rayllike
- ricefit
- ricelike
- stblfit
- stbllike
- tlsfit
- tlslike
- unidfit
- unifit
- wblfit
- wbllike
- betacdf
- betainv
- betapdf
- betarnd
- binocdf
- binoinv
- binopdf
- binornd
- bisacdf
- bisainv
- bisapdf
- bisarnd
- burrcdf
- burrinv
- burrpdf
- burrrnd
- bvncdf
- bvtcdf
- cauchycdf
- cauchyinv
- cauchypdf
- cauchyrnd
- chi2cdf
- chi2inv
- chi2pdf
- chi2rnd
- copulacdf
- copulapdf
- copularnd
- evcdf
- evinv
- evpdf
- evrnd
- expcdf
- expinv
- exppdf
- exprnd
- fcdf
- finv
- fpdf
- frnd
- gamcdf
- gaminv
- gampdf
- gamrnd
- geocdf
- geoinv
- geopdf
- geornd
- gevcdf
- gevinv
- gevpdf
- gevrnd
- gpcdf
- gpinv
- gppdf
- gprnd
- gumbelcdf
- gumbelinv
- gumbelpdf
- gumbelrnd
- hncdf
- hninv
- hnpdf
- hnrnd
- hygecdf
- hygeinv
- hygepdf
- hygernd
- invgcdf
- invginv
- invgpdf
- invgrnd
- iwishpdf
- iwishrnd
- jsucdf
- jsupdf
- laplacecdf
- laplaceinv
- laplacepdf
- laplacernd
- logicdf
- logiinv
- logipdf
- logirnd
- loglcdf
- loglinv
- loglpdf
- loglrnd
- logncdf
- logninv
- lognpdf
- lognrnd
- mnpdf
- mnrnd
- mvncdf
- mvnpdf
- mvnrnd
- mvtcdf
- mvtpdf
- mvtrnd
- nakacdf
- nakainv
- nakapdf
- nakarnd
- nbincdf
- nbininv
- nbinpdf
- nbinrnd
- ncfcdf
- ncfinv
- ncfpdf
- ncfrnd
- nctcdf
- nctinv
- nctpdf
- nctrnd
- ncx2cdf
- ncx2inv
- ncx2pdf
- ncx2rnd
- normcdf
- norminv
- normpdf
- normrnd
- plcdf
- plinv
- plpdf
- plrnd
- poisscdf
- poissinv
- poisspdf
- poissrnd
- raylcdf
- raylinv
- raylpdf
- raylrnd
- ricecdf
- riceinv
- ricepdf
- ricernd
- stblcdf
- stblinv
- stblpdf
- stblrnd
- stdrcdf
- stdrinv
- stdrpdf
- stdrrnd
- tcdf
- tinv
- tpdf
- trnd
- tlscdf
- tlsinv
- tlspdf
- tlsrnd
- tricdf
- triinv
- tripdf
- trirnd
- unidcdf
- unidinv
- unidpdf
- unidrnd
- unifcdf
- unifinv
- unifpdf
- unifrnd
- vmcdf
- vminv
- vmpdf
- vmrnd
- wblcdf
- wblinv
- wblpdf
- wblrnd
- wienrnd
- wishpdf
- wishrnd
- betastat
- binostat
- bisastat
- burrstat
- chi2stat
- copulaparam
- copulastat
- evstat
- expstat
- fstat
- gamstat
- geostat
- gevstat
- gpstat
- gumbelstat
- hnstat
- hygestat
- invgstat
- logistat
- loglstat
- lognstat
- nakastat
- nbinstat
- ncfstat
- nctstat
- ncx2stat
- normstat
- plstat
- poisstat
- raylstat
- ricestat
- stdrstat
- tlsstat
- tristat
- tstat
- unidstat
- unifstat
- wblstat
- andrewsplot
- bar3
- bar3h
- biplot
- boxchart
- boxplot
- cdfplot
- dendrogram
- ecdfhist
- einstein
- gardnerAltmanPlot
- glyphplot
- gplotmatrix
- gscatter
- heatmap
- hist3
- histfit
- manovacluster
- normplot
- parallelcoords
- parallelplot
- ppplot
- probplot
- qqplot
- scatterhist
- scatterhistogram
- silhouette
- stats.chart.BoxChart
- stats.chart.HeatmapChart
- stats.chart.ParallelCoordinatesPlot
- stats.chart.ScatterHistogramChart
- swarmchart
- violin
- wblplot
Function Reference: fitcsvm
statistics: Mdl = fitcsvm (X, Y)
statistics: Mdl = fitcsvm (Tbl, ResponseVarName)
statistics: Mdl = fitcsvm (Tbl, formula)
statistics: Mdl = fitcsvm (Tbl, Y)
statistics: Mdl = fitcsvm (…, name, value)
Fit a Support Vector Machine classification model.
Mdl = fitcsvm (X, Y) returns a Support Vector
Machine classification model, Mdl, with X being the predictor
data, and Y the class labels of observations in X.
-
Xmust be a N×P numeric matrix of predictor data where rows correspond to observations and columns correspond to features or variables. -
Yis N×1 matrix or cell matrix containing the class labels of corresponding predictor data in X. Y can be numerical, logical, char array or cell array of character vectors. Y must have same number of rows as X.
Mdl = fitcsvm (…, name, value) returns a
Support Vector Machine model with additional options specified by
Name-Value pair arguments listed below.
Model Parameters
| Name | Value |
|---|---|
'Standardize' | A boolean flag indicating whether the data in X should be standardized prior to training. |
'CategoricalPredictors' | The predictors whose values are
levels, as indices, as a logical vector with one element per predictor, or as
'all'. Each is dummy coded in its place, one column of zeros and
ones per level seen in training, named as in 'x1 == 2' in
ExpandedPredictorNames, and the coded columns are not standardized.
An observation holding a level the training data did not has no score.
A predictor may be named rather than indexed, as a character matrix of one
padded name per row, a string array or a cellstr; a name must match an entry
of 'PredictorNames' exactly, its case included. |
'PredictorNames' | A cell array of character vectors specifying the predictor variable names. The variable names are assumed to be in the same order as they appear in the training data X. |
'ResponseName' | A character vector specifying the name of the response variable. |
'ClassNames' | Names of the classes in the class
labels, Y, used for fitting the kNN model. ClassNames are of
the same type as the class labels in Y. The model keeps the classes
in this order; by default they are sorted. |
'SVMtype' | Specifies the type of SVM used for training
the ClassificationSVM model. By default, the type of SVM is defined
by setting other parameters and/or by the data itself. Setting the
'SVMtype' parameter overrides the default behavior and it accepts the
following options: |
| Value | Description |
|---|---|
'C_SVC' | It is the standard SVM formulation for
classification tasks. It aims to find the optimal hyperplane that separates
different classes by maximizing the margin between them while allowing some
misclassifications. The parameter 'C' controls the trade-off between
maximizing the margin and minimizing the classification error. It is the
default type, unless otherwise specified. |
'nu_SVC' | It is a variation of the standard SVM that
introduces a parameter ν (nu) as an upper bound on the fraction of
margin errors and a lower bound on the fraction of support vectors. This
formulation provides more control over the number of support vectors and the
margin errors, making it useful for specific classification scenarios. It is
the default type, when the 'OutlierFraction' parameter is set. |
'one_class_SVM' | It is used for anomaly detection and
novelty detection tasks. It aims to separate the data points of a single
class from the origin in a high-dimensional feature space. This method is
particularly useful for identifying outliers or unusual patterns in the data.
It is the default type, when the 'Nu' parameter is set or when there
is a single class in Y. When 'one_class_SVM' is set by the
'SVMtype' pair argument, Y has no effect and any classes are
ignored. |
| Name | Value |
|---|---|
'OutlierFraction' | The expected proportion of outliers
in the training data, specified as a scalar value in the range [0,1].
When specified, the type of SVM model is switched to 'nu_SVC' and
'OutlierFraction' defines the ν (nu) parameter. |
'KernelFunction' | A character vector specifying the
method for computing elements of the Gram matrix. The available kernel
functions are 'gaussian' or 'rbf', 'linear',
'polynomial', and 'sigmoid'. For one-class learning, the
default Kernel function is 'rbf'. For two-class learning the default
is 'linear'. |
'PolynomialOrder' | A positive integer that specifies
the order of polynomial in kernel function. The default value is 3. Unless
the 'KernelFunction' is set to 'polynomial', this parameter
is ignored. |
'KernelScale' | A positive scalar dividing every predictor
before any kernel is applied, as MATLAB does, so that with u and
v the divided predictors the kernels are u'v,
exp (-||u - v||^2), (1 + u'v)^q and tanh (u'v + c),
c being 'KernelOffset'. The default is 1. |
'KernelOffset' | A non-negative scalar, the constant c of the sigmoid kernel, which MATLAB does not have. MATLAB adds it to every element of the Gram matrix, which leaves the fitted model unchanged, so it changes no other kernel here. The default is 0. |
'Weights' | A single or double vector of nonnegative
observation weights, one per row of X. Each observation’s box
constraint is n times BoxConstraint times its weight, the
weights scaled so that each class carries its prior times the cost of
misclassifying it. An empirical prior sums the weights per class,
standardization uses weighted means and standard deviations, and a row of
zero weight is left out. The model’s W keeps the class of the
weights, while every computation runs in double, so Prior is double
where MATLAB returns single. |
'BoxConstraint' | A positive scalar that specifies the
upper bound of the Lagrange multipliers, i.e. the parameter C, which is used
for training 'C_SVC' and 'one_class_SVM' type of models. It
determines the trade-off between maximizing the margin and minimizing the
classification error. The default value for 'BoxConstraint' is 1. |
'Nu' | A positive scalar, in the range (0,1]
that specifies the parameter ν (nu) for training 'nu_SVC' and
'one_class_SVM' type of models. Unless overridden by setting the
'SVMtype' parameter, setting the 'Nu' parameter always forces
the training model type to 'one_class_SVM', in which case, the number
of classes in Y is ignored. The default value for 'Nu' is 1. |
'CacheSize' | A positive scalar that specifies the memory requirements (in MB) for storing the Gram matrix. The default is 1000. |
'Tolerance' | A nonnegative scalar that specifies the tolerance of termination criterion. The default value is 1e-6. |
'Shrinking' | Specifies whether to use shrinking heuristics. It accepts either 0 or 1. The default value is 1. |
Cross Validation Options
| Name | Value |
|---|---|
'Crossval' | Cross-validation flag specified as
'on' or 'off'. If 'on' is specified, a 10-fold
cross validation is performed and a ClassificationPartitionedModel is
returned in Mdl. To override this cross-validation setting, use only
one of the following Name-Value pair arguments. |
'CVPartition' | A cvpartition object that
specifies the type of cross-validation and the indexing for the training and
validation sets. A ClassificationPartitionedModel is returned in
Mdl and the trained model is stored in the Trained property. |
'Holdout' | Fraction of the data used for holdout
validation, specified as a scalar value in the range [0,1]. When
specified, a randomly selected percentage is reserved as validation data and
the remaining set is used for training. The trained model is stored in the
Trained property of the ClassificationPartitionedModel returned
in Mdl. 'Holdout' partitioning attempts to ensure that each
partition represents the classes proportionately. |
'KFold' | Number of folds to use in the cross-validated
model, specified as a positive integer value greater than 1. When specified,
then the data is randomly partitioned in k sets and for each set, the
set is reserved as validation data while the remaining k-1 sets are
used for training. The trained models are stored in the Trained
property of the ClassificationPartitionedModel returned in Mdl.
'KFold' partitioning attempts to ensure that each partition
represents the classes proportionately. |
'Leaveout' | Leave-one-out cross-validation flag
specified as 'on' or 'off'. If 'on' is specified,
then for each of the n observations (where n is the number of
observations, excluding missing observations, specified in the
NumObservations property of the model), one observation is reserved as
validation data while the remaining observations are used for training. The
trained models are stored in the Trained property of the
ClassificationPartitionedModel returned in Mdl. |
See also: ClassificationSVM, ClassificationPartitionedModel, svmtrain, svmpredict
Source Code: fitcsvm
Use a subset of Fisher's iris data set
 load fisheriris
 inds = ! strcmp (species, 'setosa');
 X = meas(inds, [3,4]);
 Y = species(inds);
Train a linear SVM classifier
SVMModel = fitcsvm (X, Y)
SVMModel =

  ClassificationSVM

             ResponseName: 'Y'
               ClassNames: {'versicolor' 'virginica'}
           ScoreTransform: 'none'
          NumObservations: 100
            NumPredictors: 2
                    Alpha: [24x1 double]
                     Beta: [2x1 double]
                     Bias: -14.414868
         KernelParameters: [1x1 struct]
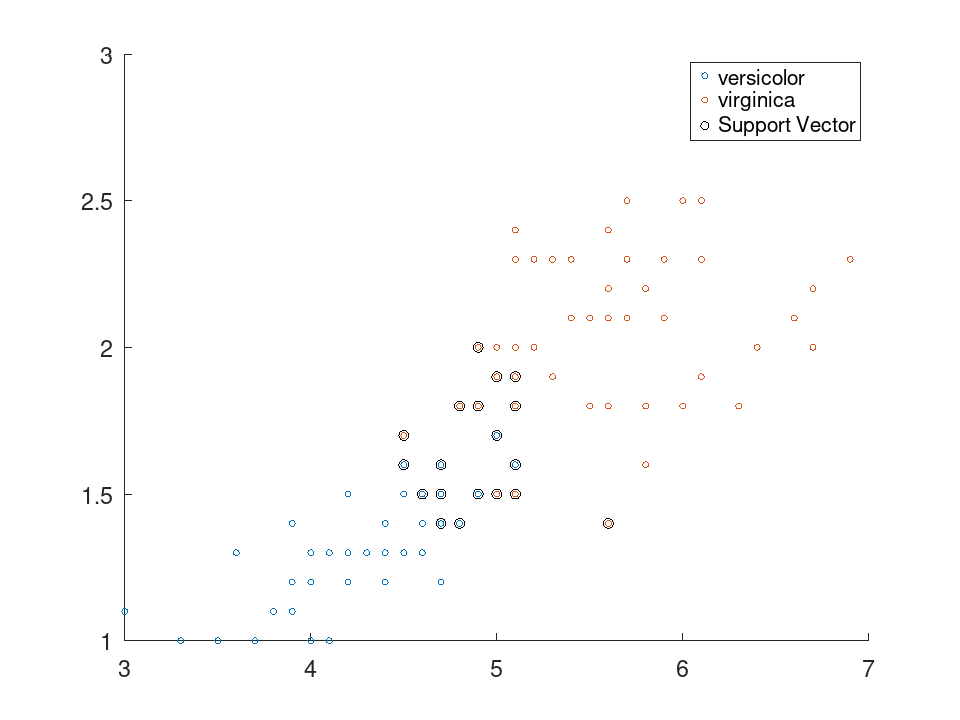
Plot a scatter diagram of the data and circle the support vectors.
 sv = SVMModel.SupportVectors;
 figure
 gscatter (X(:,1), X(:,2), Y)
ans =

  -226.84  -225.62
 hold on
 plot (sv(:,1), sv(:,2), 'ko', 'MarkerSize', 10)
 legend ('versicolor', 'virginica', 'Support Vector')
 hold off
Fit from a table, and predict on one
 load fisheriris
 inds = ! strcmp (species, 'setosa');
 X = meas(inds,:);
 T = table (X(:,1), X(:,2), X(:,3), X(:,4), ...
            'VariableNames', {'SL', 'SW', 'PL', 'PW'});
 T.Species = categorical (species(inds));
A column holding levels is a categorical predictor without being named one
T.Wide = categorical (X(:,2) > 2.9, [false true], {'narrow', 'wide'});
The response is named by its column, and everything else is a predictor
 Mdl = fitcsvm (T, 'Species');
 Mdl.PredictorNames
ans =
  1x5 cell array

    {'SL'}    {'SW'}    {'PL'}    {'PW'}    {'Wide'}
Mdl.CategoricalPredictors
ans = 5
predict reads a table by the names the model was fitted on, so the columns may come in any order
 label = predict (Mdl, T(1:5, [6, 5, 4, 3, 2, 1]));
 label'
ans =
  1x5 categorical array

    versicolor    versicolor    versicolor    versicolor    versicolor